Best LLM for Coding in 2026: What the Benchmarks Actually Say
Read coding benchmarks with their dataset, agent and effort settings; compare current models and total cost on representative repository work.
TL;DR: Shortlist Claude Opus 5.5 and GPT-6 Astra for demanding coding, then compare their complete agent setups on your repository because benchmark versions, tools and evaluation rules change the result.
Checked 6 November 2026. A reproducible result needs more than a model name and a percentage. Keep the dataset version, agent harness and reasoning setting beside every score, and distinguish a published experiment from today's available models.
What benchmarks actually measure coding ability?
Repository repair, exercise editing and terminal automation test different work. Start with the kind of work the evaluation tests:
| Benchmark | What it tests | Best for | Reading caution |
|---|---|---|---|
| SWE-bench Verified | 500 human-filtered repository issues | Historical issue-repair comparisons | Use the same agent setup and inspect task quality. |
| SWE-Bench Pro V2 | Revised repository-level tasks | Longer bug fixes across existing projects | Keep V1, V2 and Hard results separate. |
| Aider polyglot | 225 exercises across six languages | Editing existing code through Aider | Check attempt count and the date of each run. |
| Terminal-Bench | Tasks completed through a terminal environment | Agents running tools and producing artifacts | Specify the version and model-agent pair. |
The SWE-bench maintainers distinguish their human-filtered Verified subset from the original dataset. Their current default Verified view uses a common mini-SWE-agent environment. That view is different from combining submissions made with unrelated agent scaffolds.
Aider's published results cover C++, Go, Java, JavaScript, Python and Rust. Its displayed GPT-5 high row reports 88.0% after two passes, with a run date of 23 August 2025; the first-pass result is 52.0%. Reading the page today does not make that a November 2026 experiment or a single-attempt success rate.
Why is the most-cited coding benchmark inflated?
Public tests can suffer from data exposure, weak grading and incomplete instructions. Those are separate problems: a high score alone cannot tell you how much came from memorisation. A lower score on another dataset cannot measure that amount either.
The SWE-Bench Pro V2 release revises tasks and evaluation rules, rather than simply subtracting a contaminated portion from an old score. It restricts agent network access and re-grades patches in a clean environment. Such controls reduce particular failure paths; they do not prove that every task or every future submission is contamination-free.
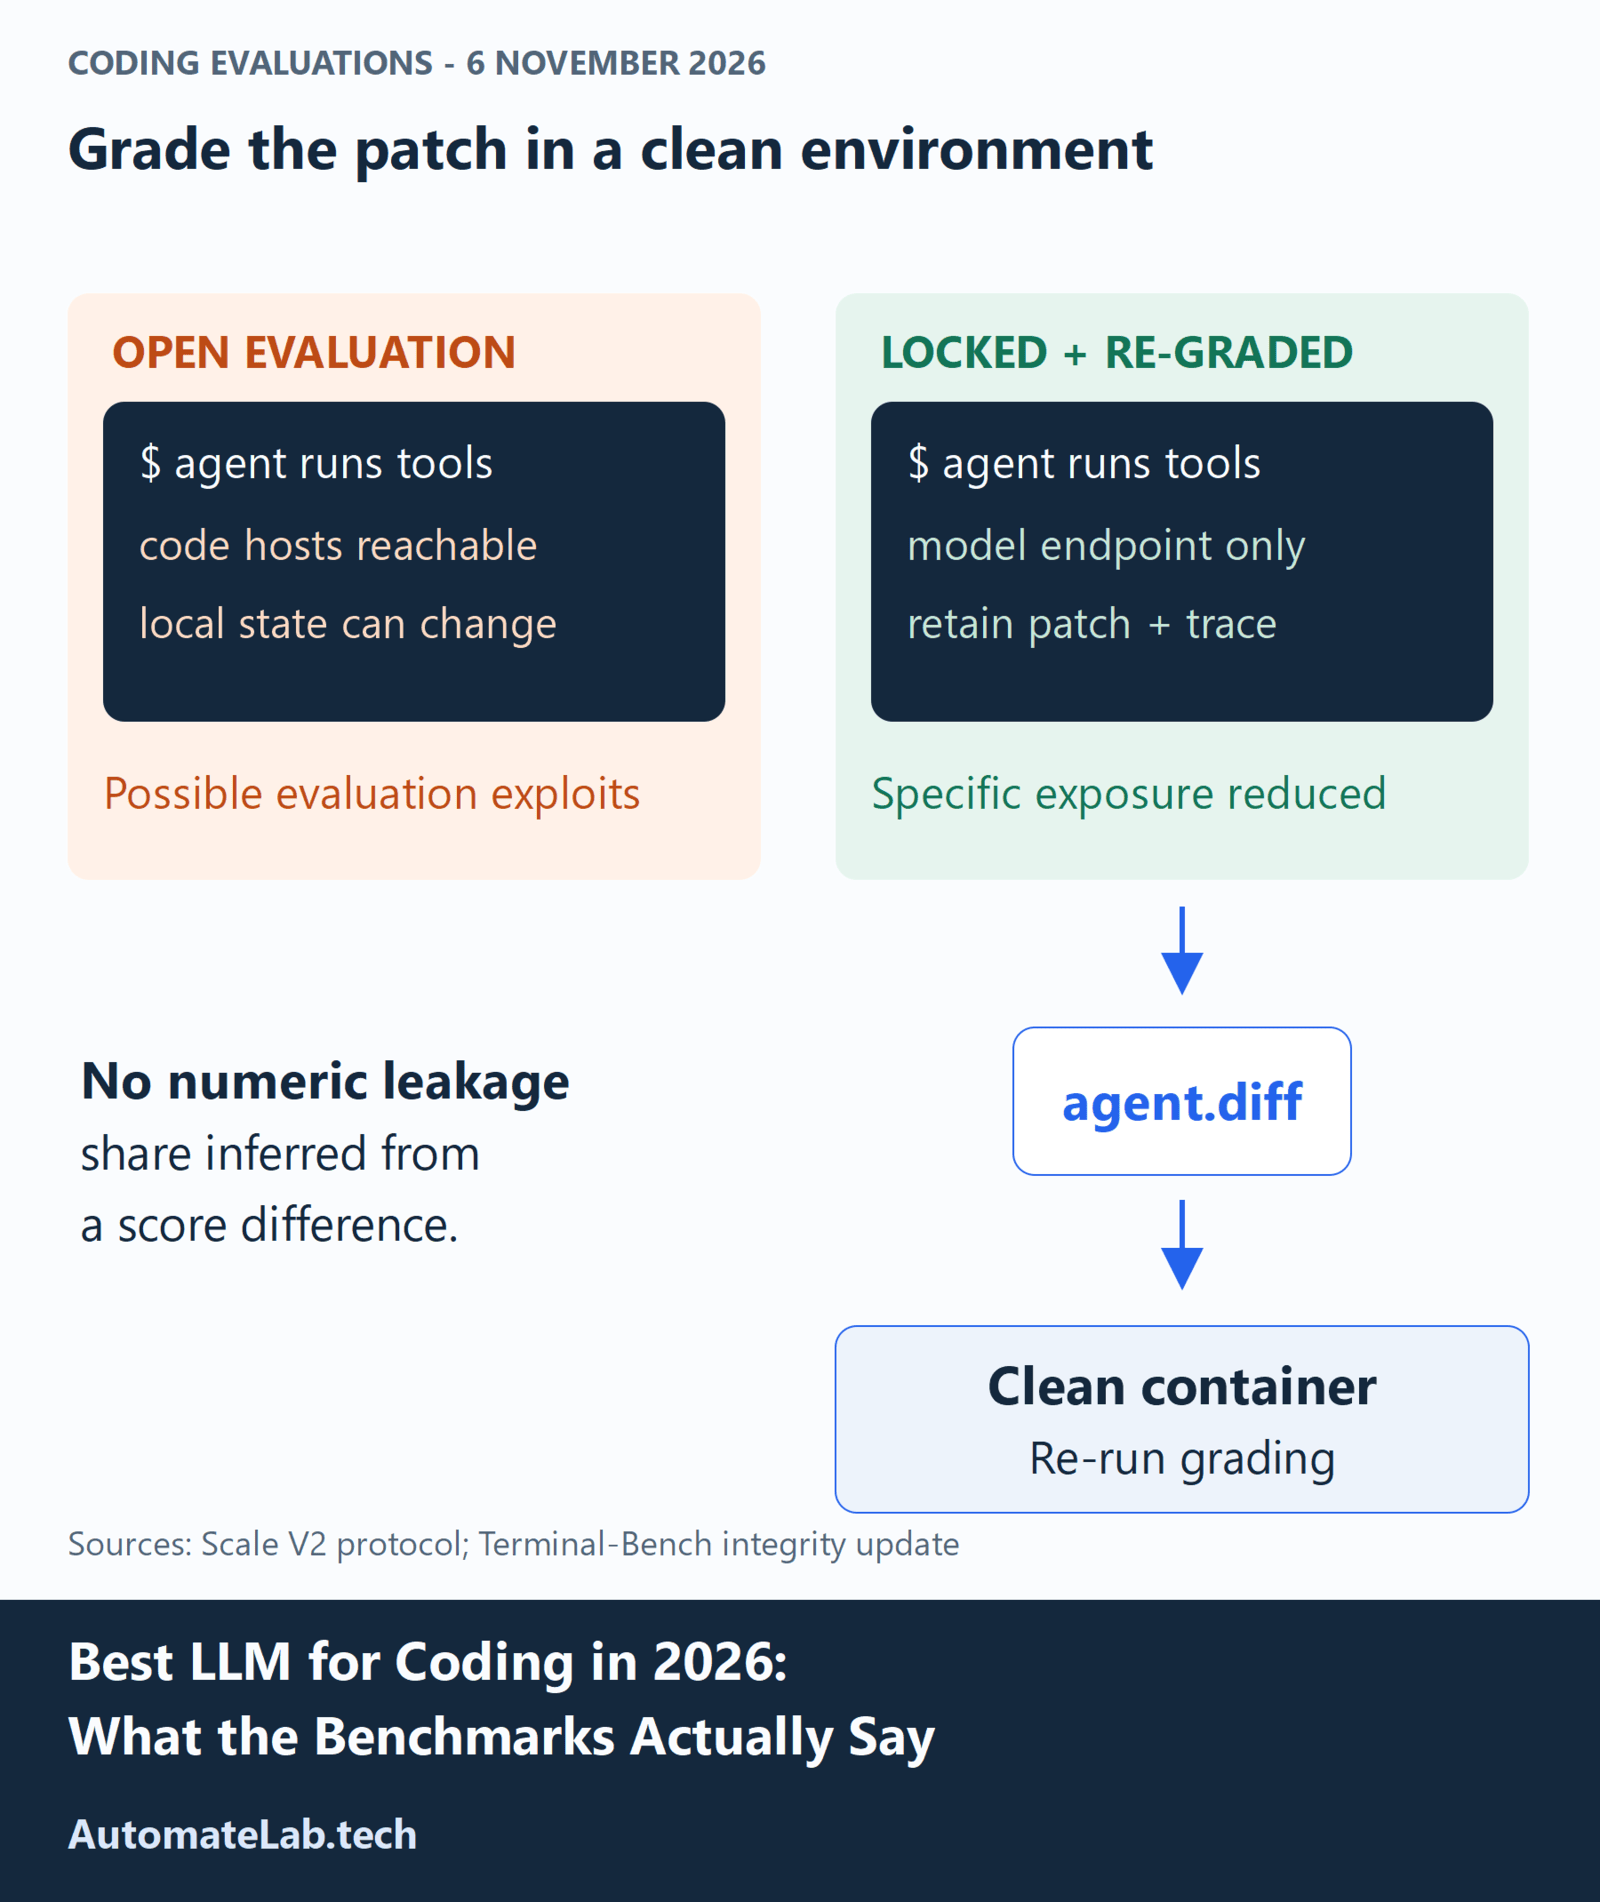
Terminal-Bench's integrity update separately documents reward hacking and cheating. Its policy requires passing trajectories, assigns zero to reward-hacking trials and removes cheating submissions. An agent can exploit its test environment without having memorised the answer during training.
Which models lead in 2026?
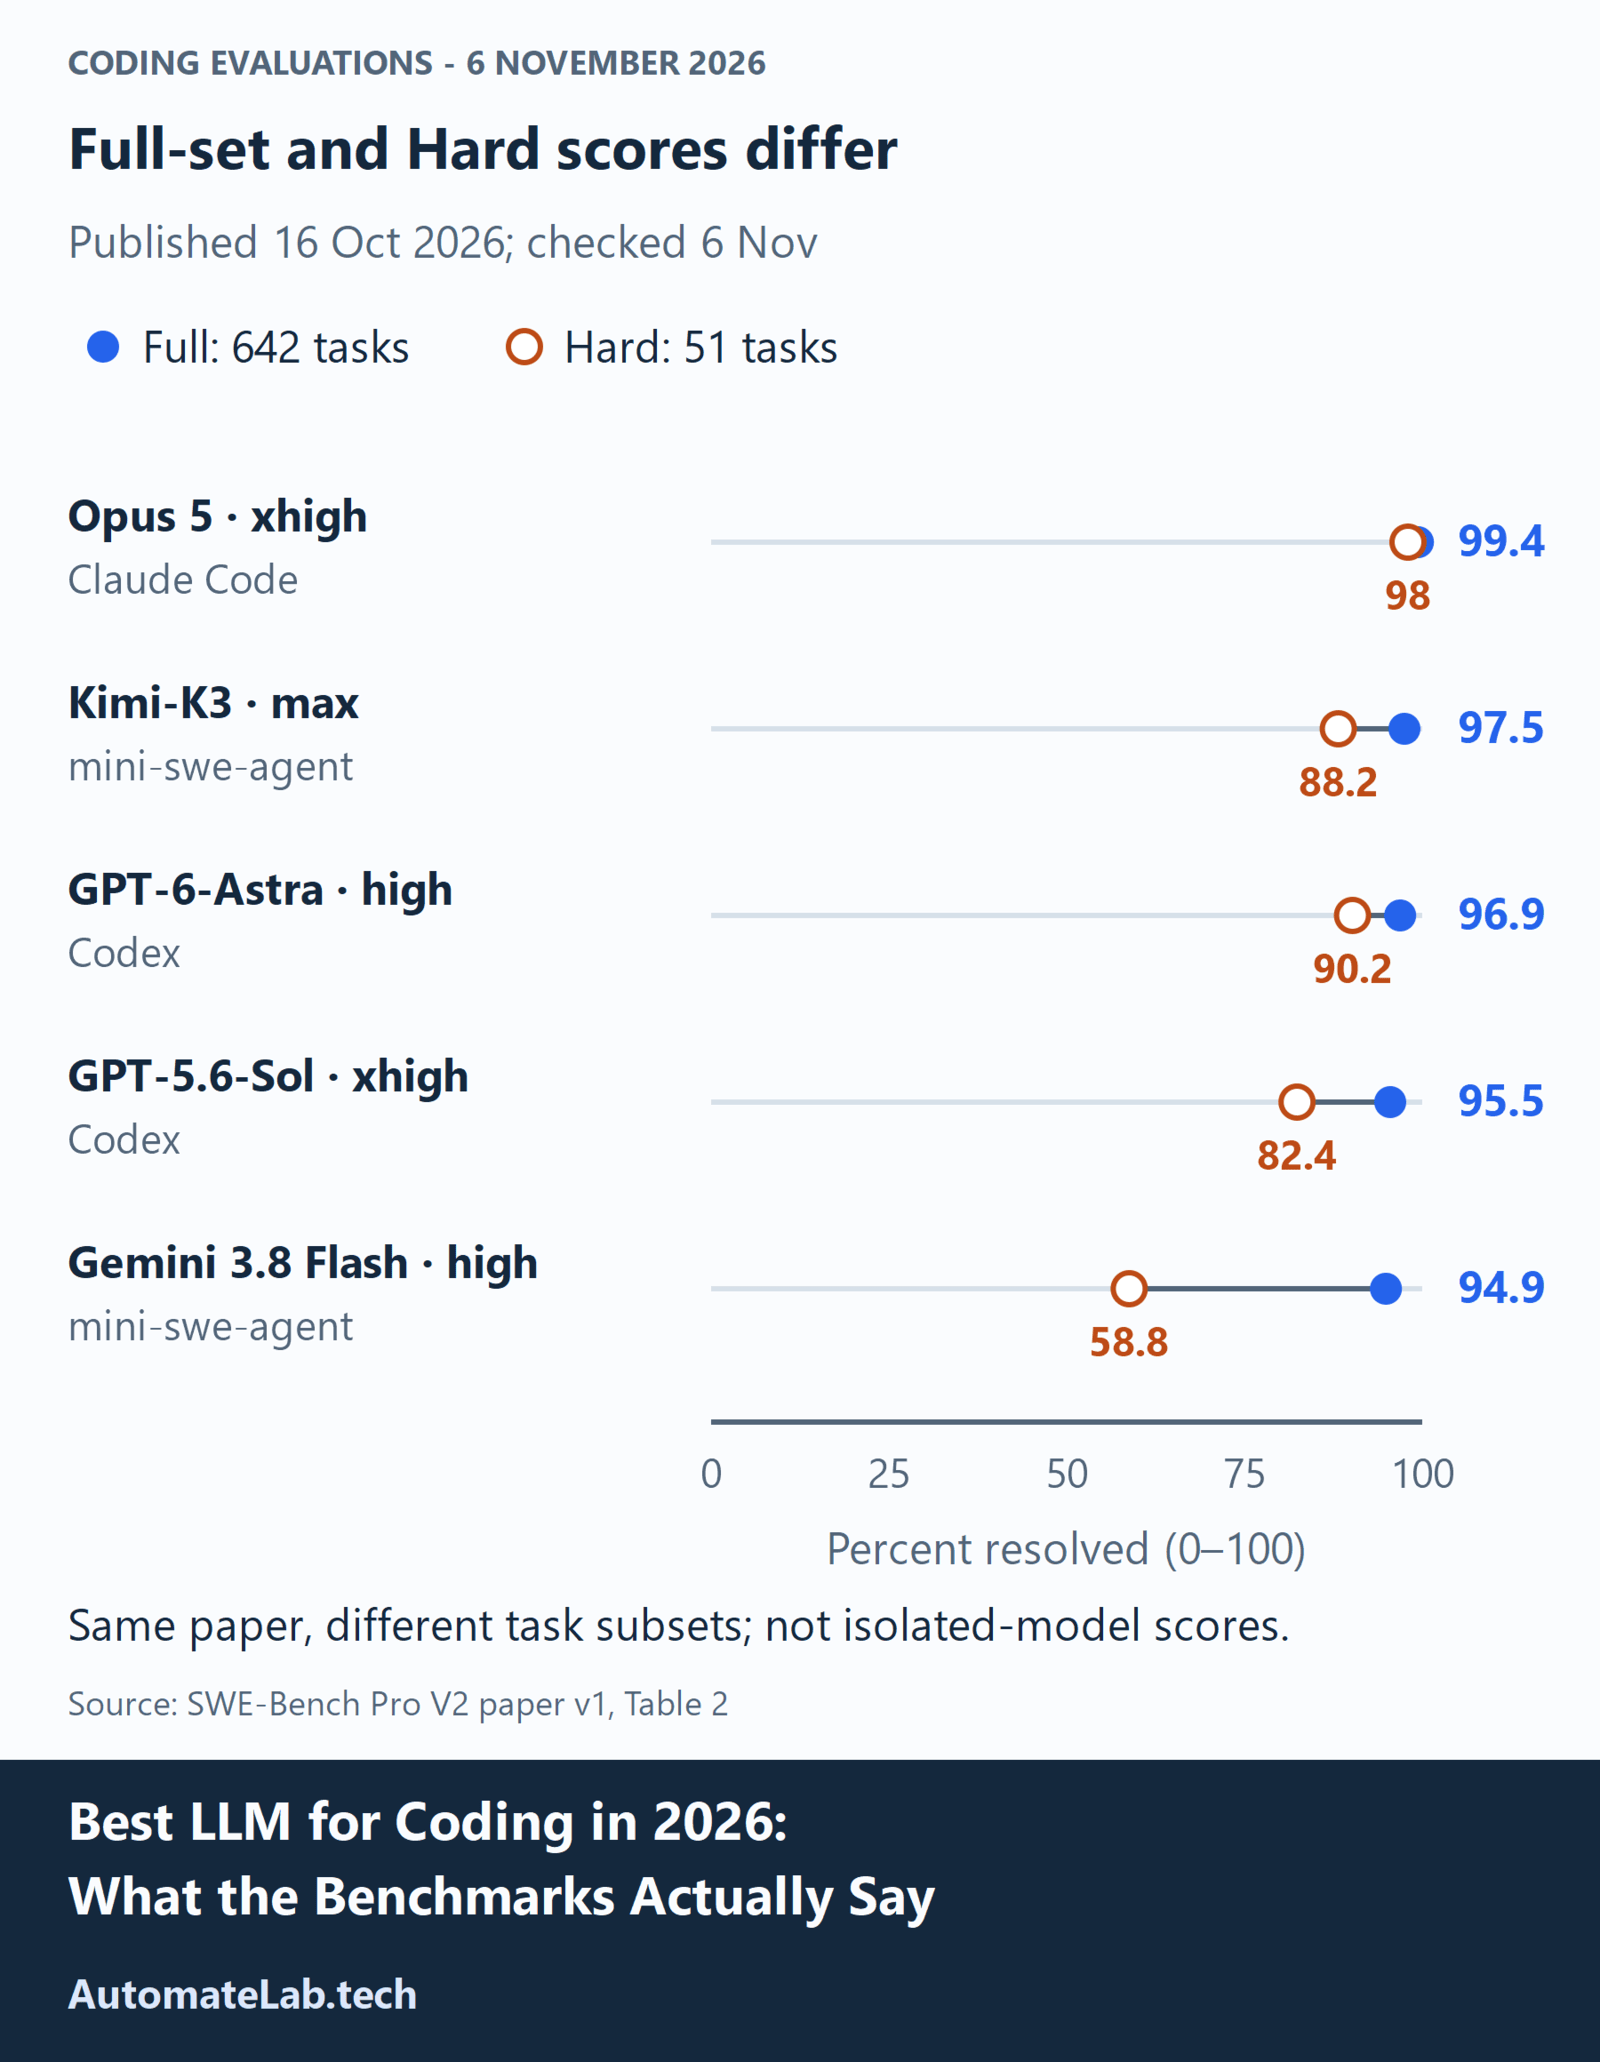
The table below is a reproducible published snapshot, not a complete ranking of every model available today. It transcribes selected rows from Table 2 of the 16 October SWE-Bench Pro V2 paper, checked today. Higher percentages mean more resolved tasks within that evaluation.
| Published model and effort | Agent | V2, 642 tasks | Hard, 51 tasks |
|---|---|---|---|
| Opus 5, xhigh | Claude Code | 99.4% | 98.0% |
| Kimi-K3, max | mini-swe-agent | 97.5% | 88.2% |
| GPT-6-Astra, high | Codex | 96.9% | 90.2% |
| GPT-5.6-Sol, xhigh | Codex | 95.5% | 82.4% |
| Gemini 3.8 Flash, high | mini-swe-agent | 94.9% | 58.8% |
The paper uses a 50-minute task budget. These are system results, including the agent and effort setting, rather than isolated model measurements. Its Hard subset produces a different spread from the full set; neither column converts into a predicted success rate for your backlog.
Check which models are available before building the shortlist. Anthropic's model guide now recommends Opus 5.5 as its starting point for most work. OpenAI's catalog names GPT-6 Astra for complex reasoning and coding, and GPT-6.1 Sol for balancing intelligence and cost. Do not transfer the Opus 5 or GPT-5.6-Sol scores above onto those newer model names.
Prices checked November 2026: approximate euros per million standard API tokens, input/output, before tax. Vendor dollar rates are converted using the 5 November ECB rate of 1.1224 dollars per euro; these are not euro checkout quotes. Caching, batch discounts and tool charges need separate treatment.
| Current candidate | Approximate input/output price | Best trial use |
|---|---|---|
| Claude Opus 5.5 | €3.56 / €17.82 | Demanding changes in the Claude workflow. |
| GPT-6 Astra | €8.91 / €44.55 | Complex work in an OpenAI agent setup. |
| GPT-6.1 Sol | €1.78 / €8.91 | A lower-cost candidate on the same repository tasks. |
What is the best LLM for each coding task?
For repository bugs, compare agents that can inspect files and run the relevant tests. For exercise-style edits, examine language coverage and edit format. For terminal work, the Terminal-Bench site currently presents version 4.0; an older 2.0 link must not silently turn into a 4.0 score claim.
For bulk routine changes, trial a cheaper candidate beside a flagship and measure accepted patches per total spend. For offline work, check weight availability, licence and hardware requirements before promising local control. Open weights alone establish neither a private deployment nor that an ordinary laptop can serve the model.
How do you choose an LLM for your own codebase?
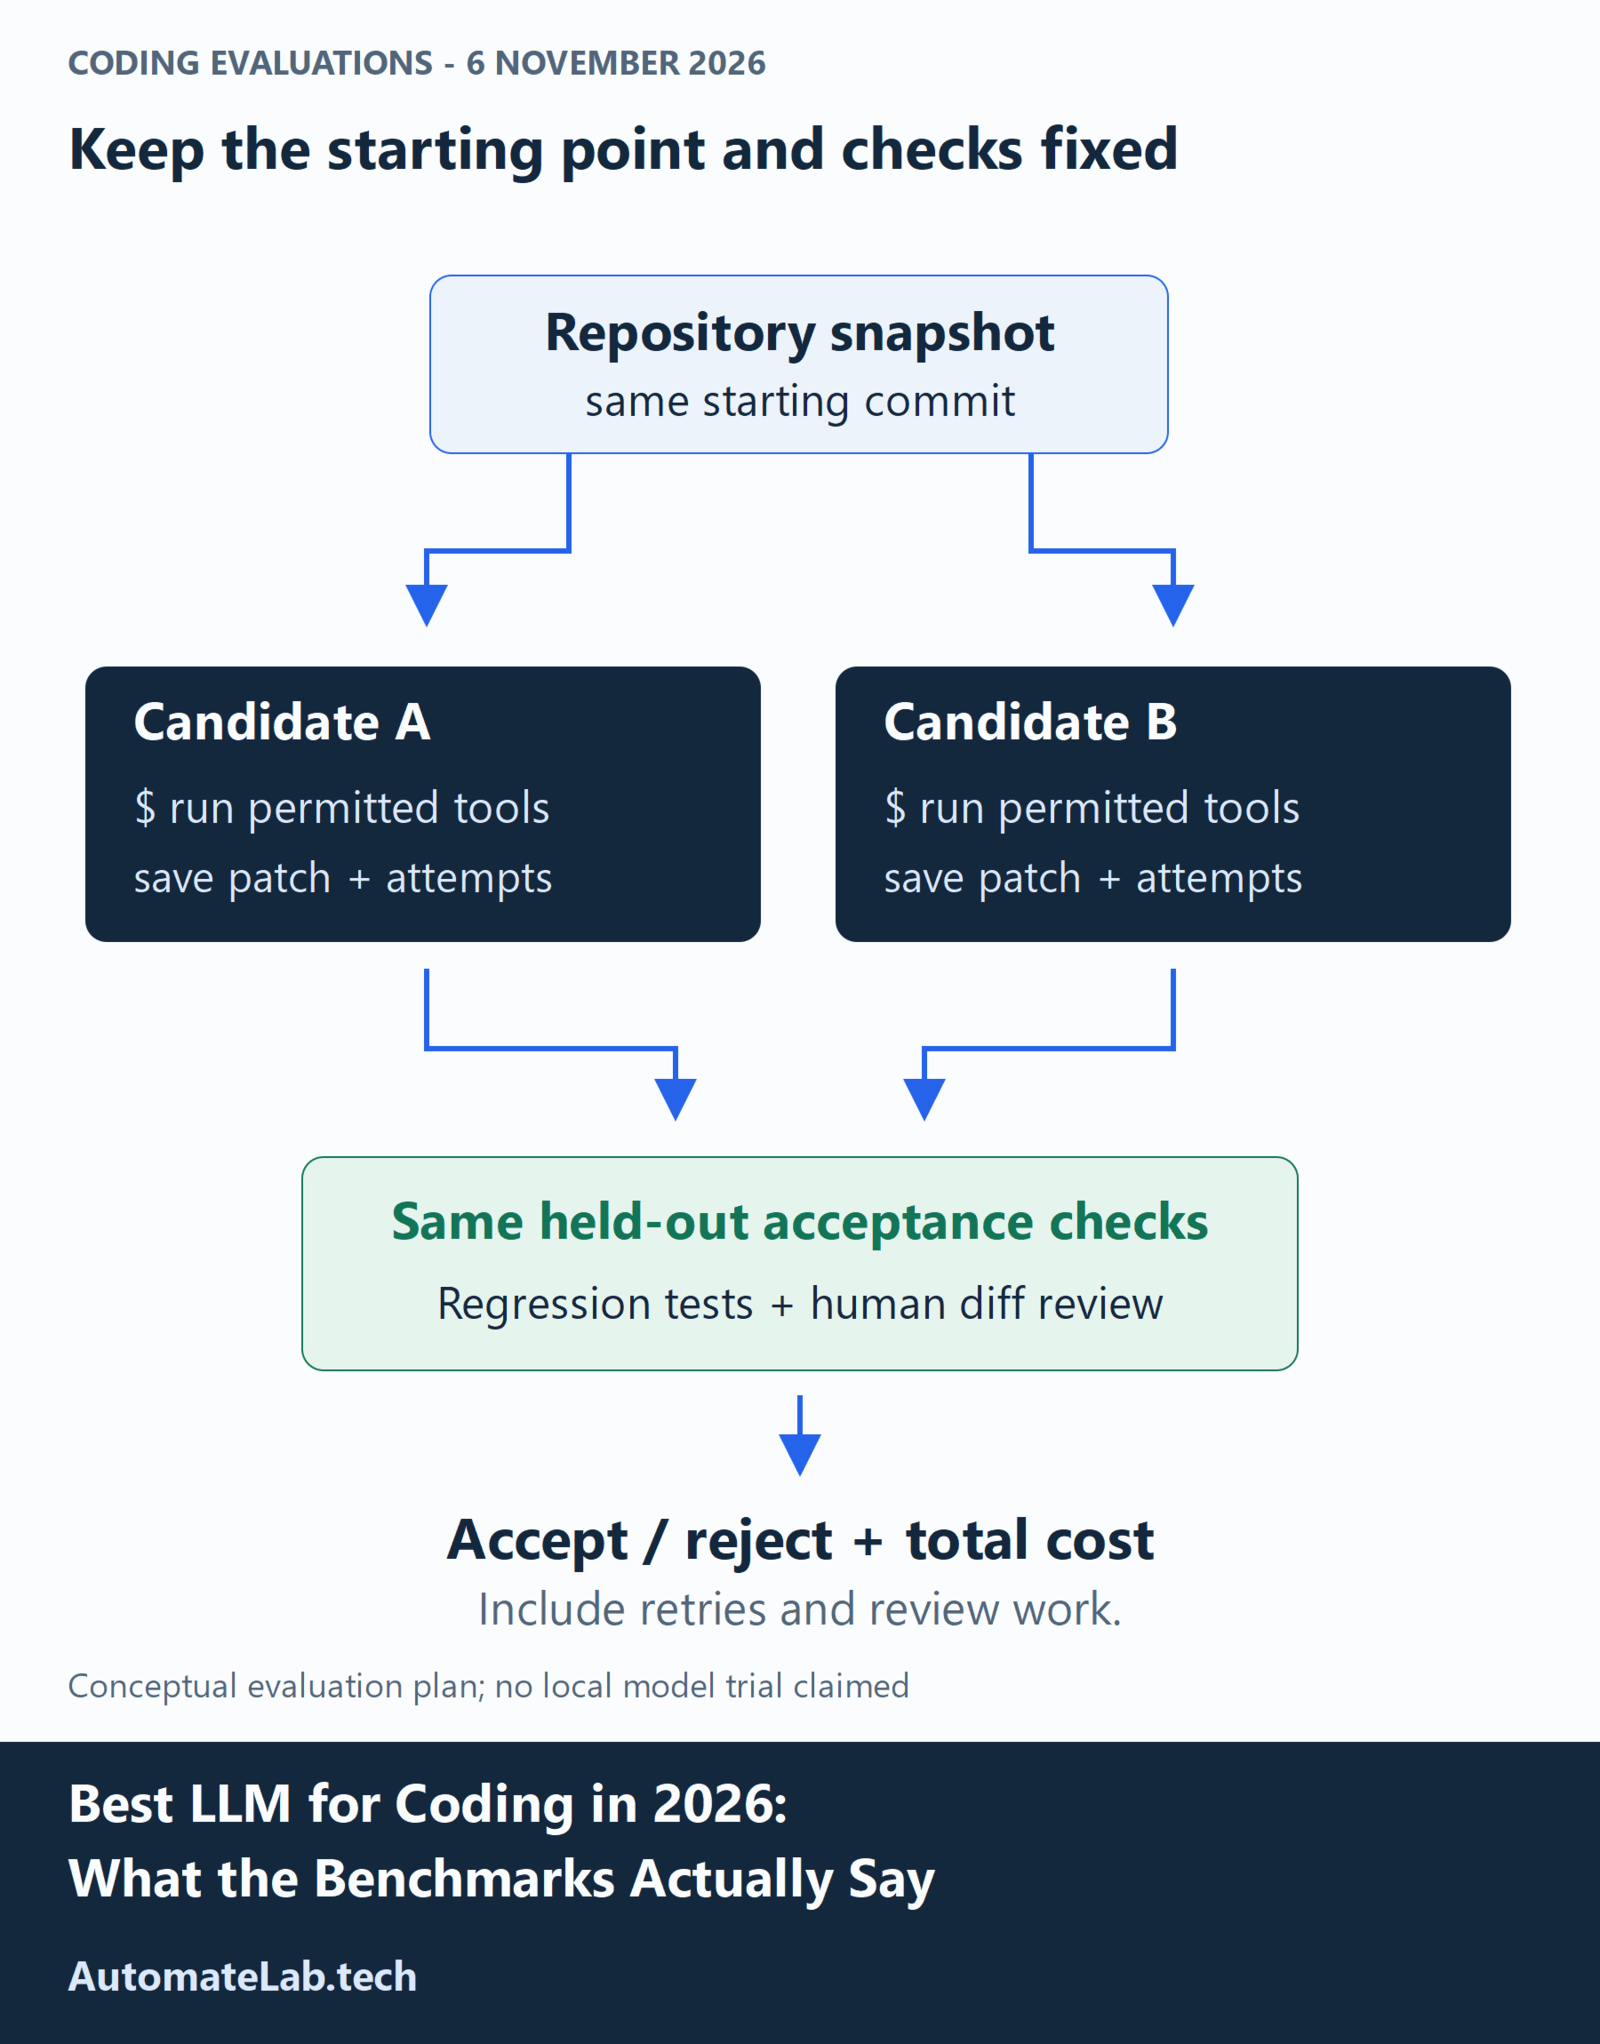
Run the same representative tasks on clean copies of the repository. Give each candidate the same starting commit, instructions and permitted tools. Hide the acceptance checks until after it produces a patch, and retain failures as well as successes. A change that passes a visible test can still remove functionality or weaken a check.
Record the exact model ID, effort, harness version and retry allowance. Review regressions, unnecessary scope and the time needed to make the patch mergeable. Include input/output tokens and repeated attempts in cost. This is an evaluation plan, not a claim that AutomateLab ran these models on a production repository.
Compare the surrounding workflow using the Codex versus Claude Code guide. The MCP configuration guide helps define consistent tool access. Additional tools can change both the result and the permissions needed to reproduce it.
How do you pick the right coding model in four steps?
- Match the benchmark task and version to the work you need.
- Record the model, harness, effort and evaluation protocol beside each score.
- Trial current candidates on identical repository snapshots with held-out acceptance checks.
- Choose using reviewed patches, regressions and total cost including retries.
FAQ
What is the best LLM for coding in 2026?
Opus 5.5 and GPT-6 Astra are current candidates for demanding coding. Benchmark results depend on the agent and task, so compare their complete setups on your repository before choosing.
Is SWE-bench Verified reliable?
Use it with its dataset and agent context. It is a human-filtered benchmark, but a high percentage does not establish immunity to data exposure, grading defects or evaluation exploits.
Which benchmark should I trust for coding?
Use repository benchmarks for issue repair, Aider for code editing and Terminal-Bench for terminal tasks. Compare matching versions and protocols, then verify the shortlist on your own work.
Is a bigger model always better for coding?
No universal size rule chooses the best value. Compare accepted changes and total spend on the same tasks; fewer retries or less review work can offset a higher token price.
Can open-weight models handle coding?
They are candidates for coding evaluations, but capability and deployment requirements vary. Check the exact weights, licence, serving hardware and permitted network access before treating an option as local or private.